llama.cpp Can Now Compute Missed MoE Experts on the CPU
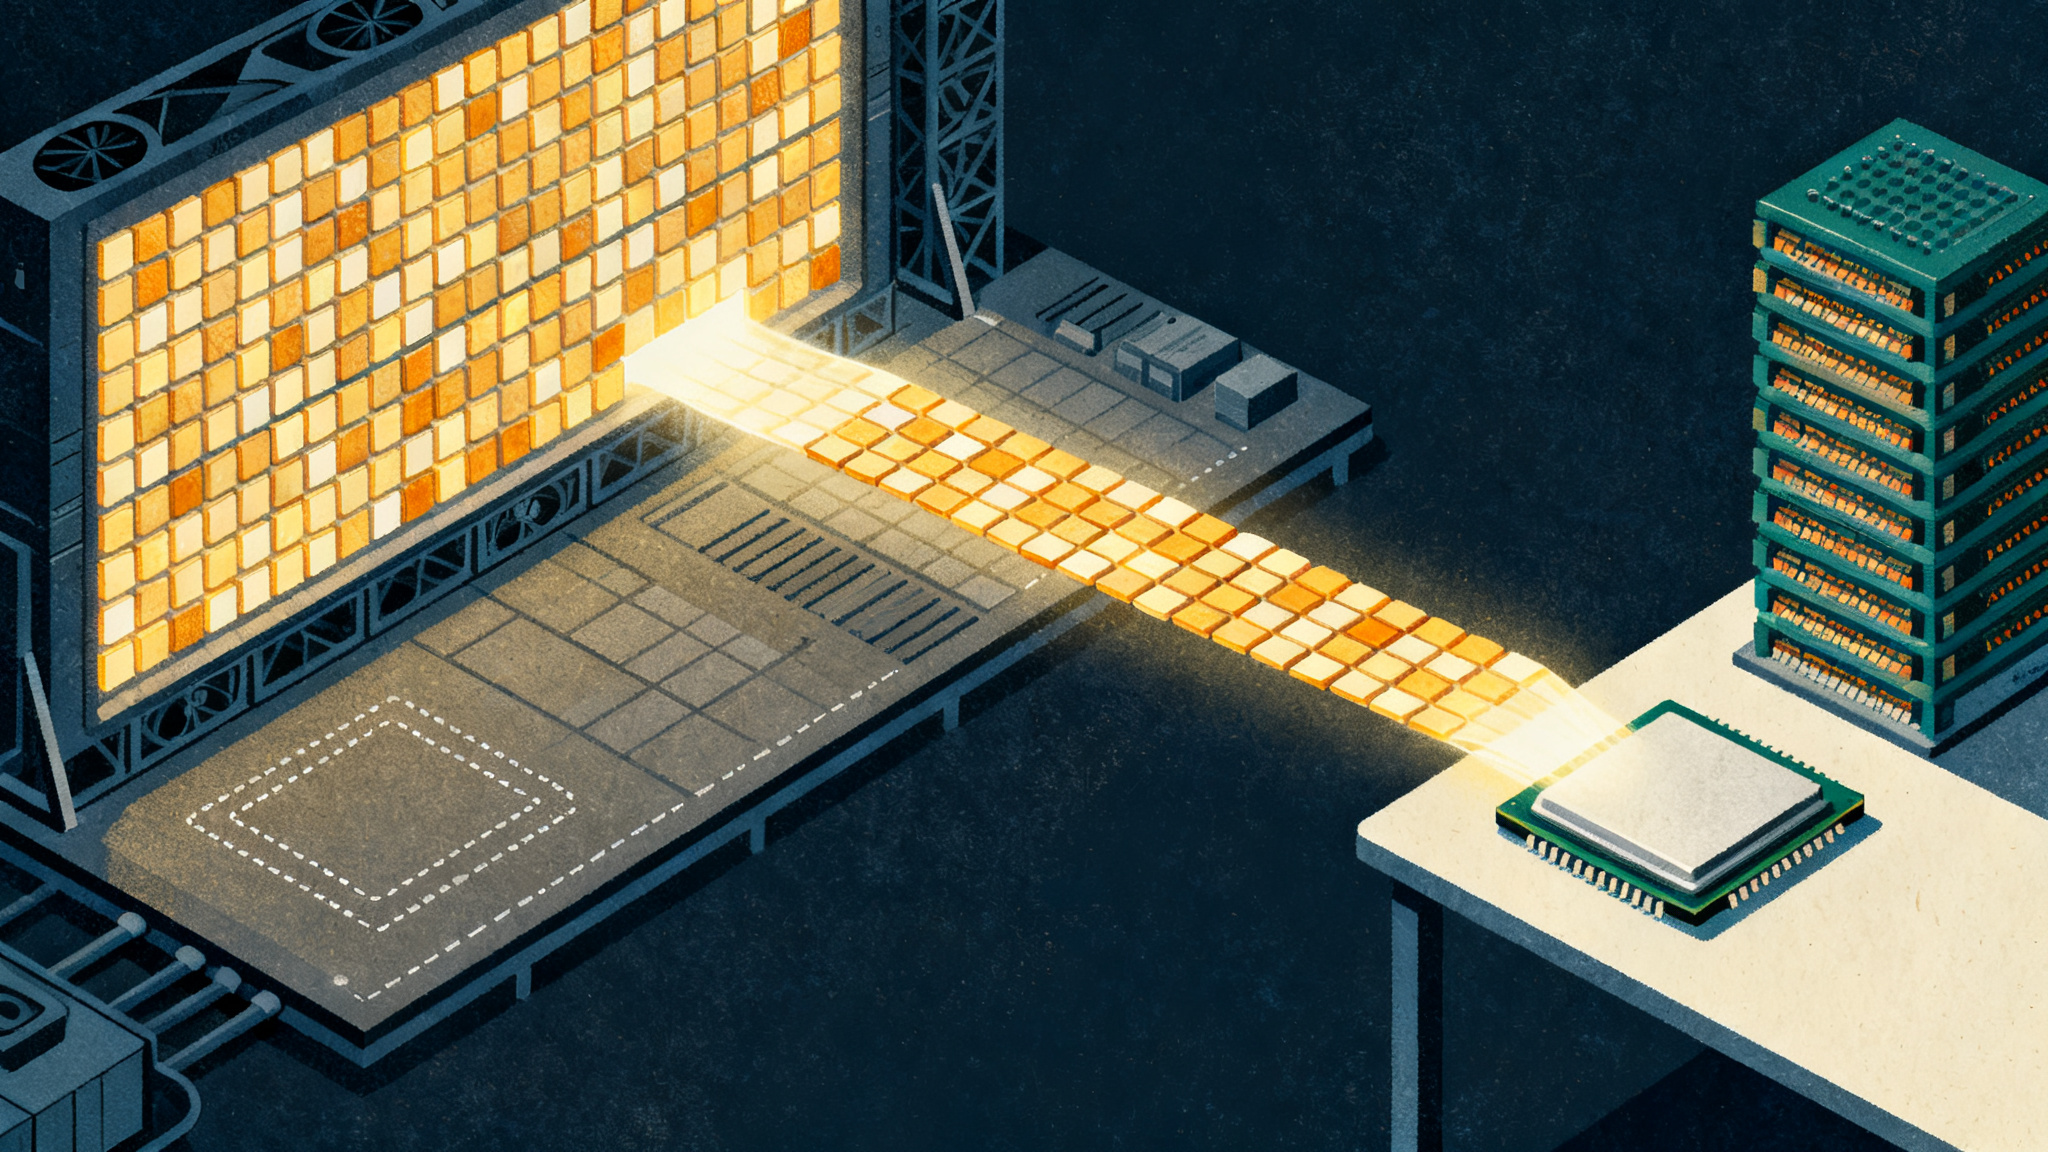
llama.cpp pull request 30966 gives the CPU an actual job in mixture-of-experts inference. When the GPU's expert cache is full and a routed expert isn't in it, the CPU computes that expert from host RAM instead of waiting around for the upload. The switch is