Flash-dLLM's 11x Speedup for Diffusion Language Models
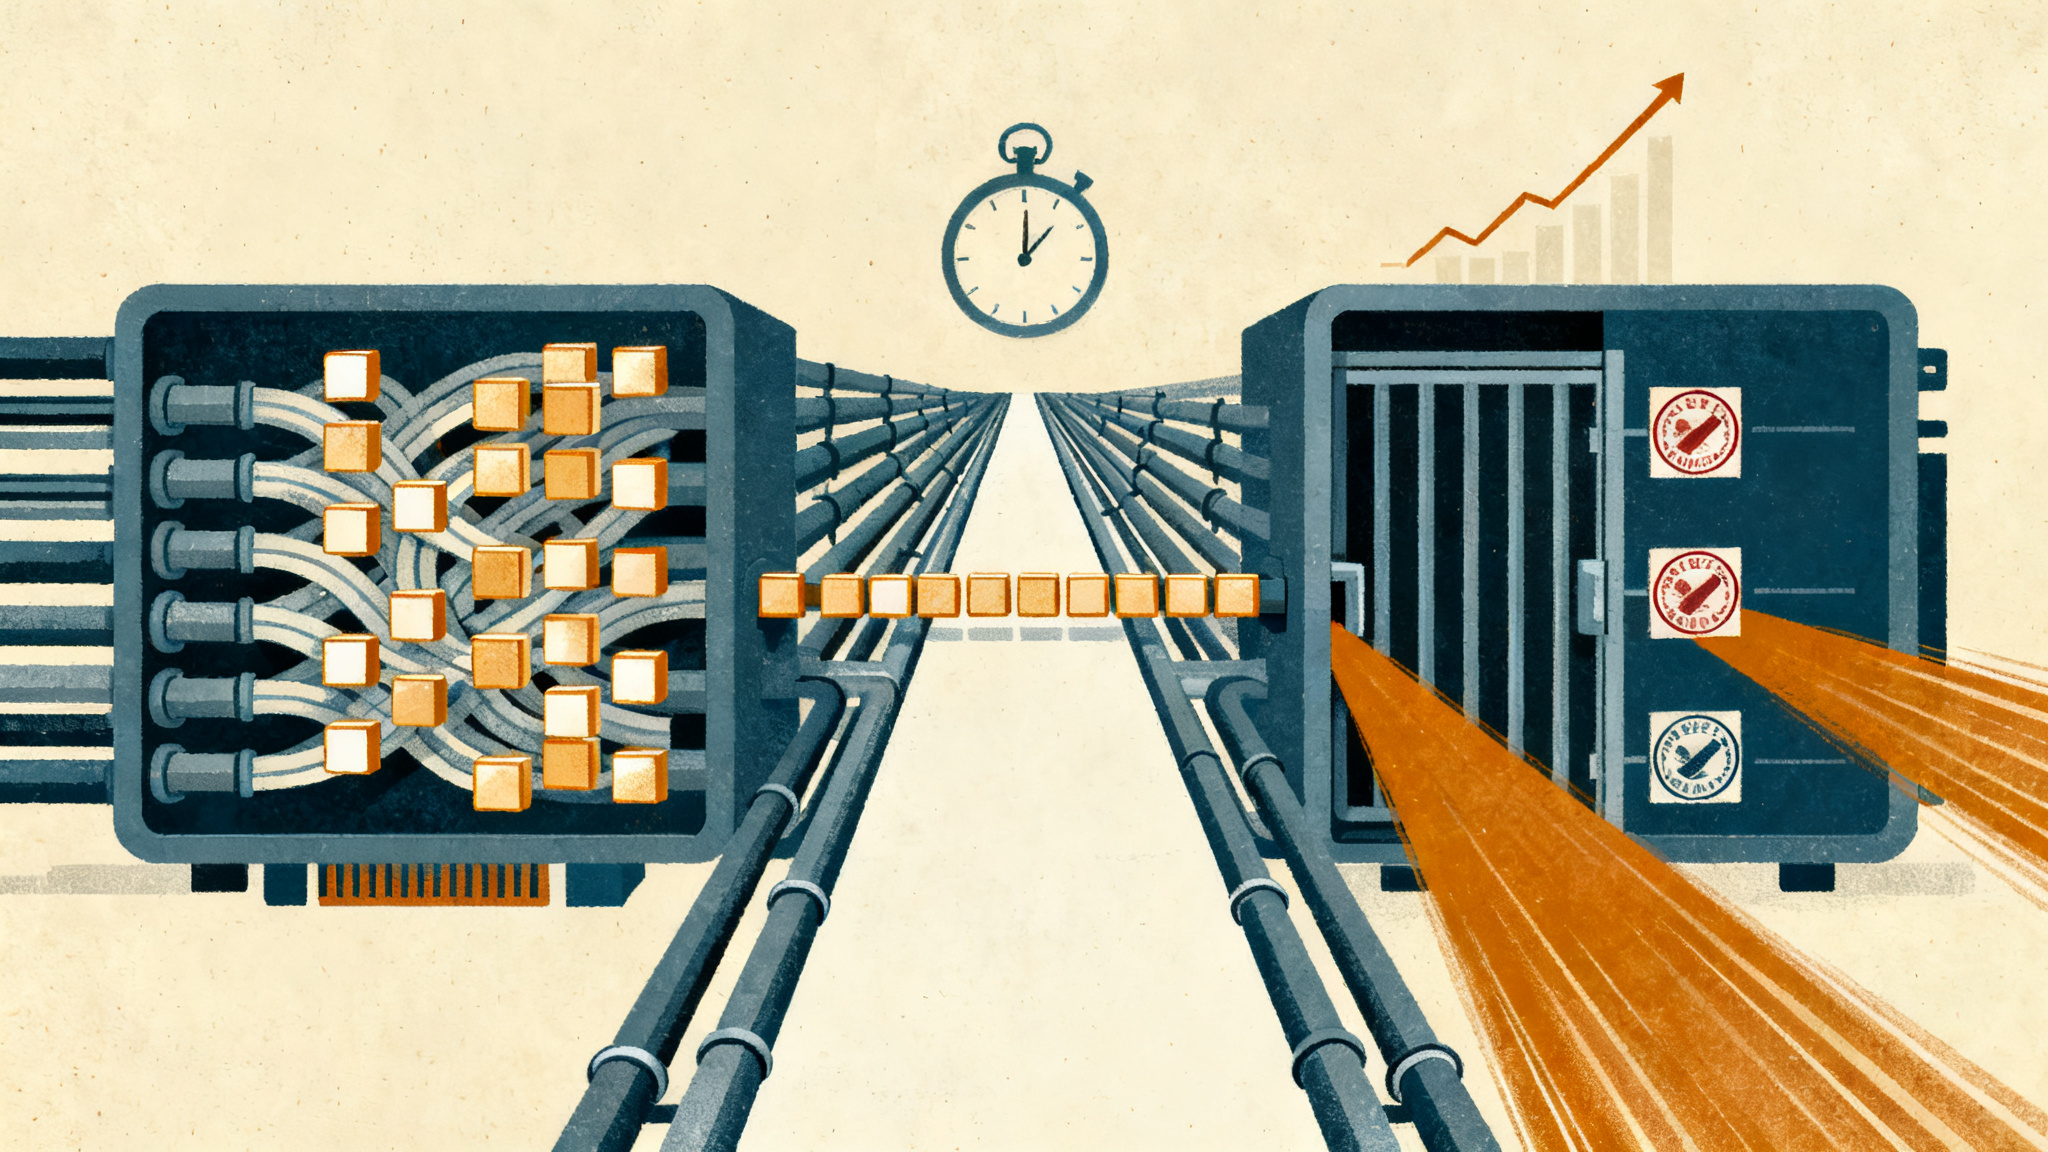
Flash-dLLM reports 11x faster diffusion language model inference. And the claim comes with a named baseline: a 5.1x speedup on GSM8K and an 11.0x speedup on HumanEval over the prior strongest acceleration method, Elastic-Cache (paper listing). The framework, from authors Quan Nguyen-Tri, Mukul Ranjan. And Zhiqiang Shen, is